


Tencent's media AI models, WAND, are now open to all — take media creativity from imagination to delivery, all in one place

WAND
Enhance+
EraseVibe+
Vega
Codec+
Vega VL
Vega Audio
Video Enhancement Model
WAND-Enhance+ is a video enhancement model built on a DiT foundation model. Global context modeling reconstructs authentic texture detail for a generational leap in clarity and vividness. Capabilities include 4K super-resolution, intelligent frame interpolation (up to 120 FPS), compression artifact removal, SDR2HDR, and face enhancement.
A woman slowly opens her eyes in the courtyard and begins practicing tai chi, the wind from her movements swirling the fallen leaves upward, keeping the same visual style throughout
 WAND-Vega
Video ParametersH.2644K
Gentle LadyEnglish
Launch Products Faster with WAND
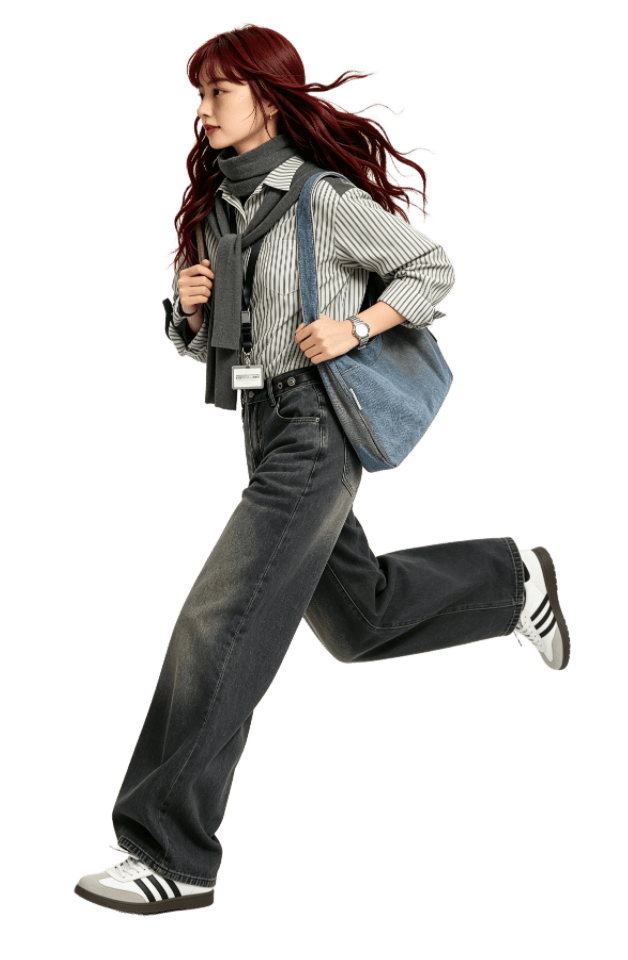
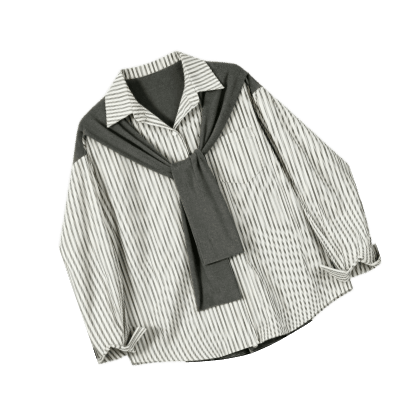
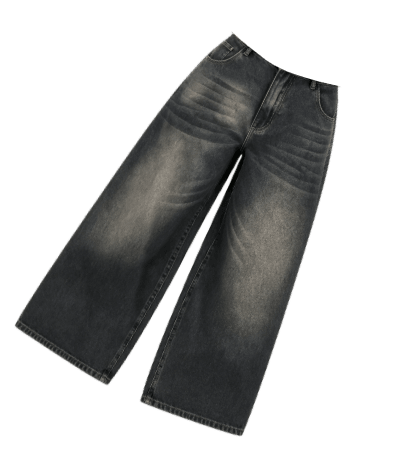
Dress the model in these clothes
AI Try-On
Product Visuals
Retouch & Cutout
Product Videos
Text & Logo Removal
Watermark & Trace
Convert to anime style, keep characters consistent
Generate a script and storyboard
Script & Storyboard
Video Restyling
Character Consistency
Smart Dubbing & Localization
Subtitle / Seamless Erasing
Quality Enhancement & TSC Encoding
Switch this live stream from horizontal to vertical and translate English into Chinese
AI Commentary & Directing
Live Highlights
AI Live Reframing
Live 4K Super-Resolution
Multilingual Subtitles & Dubbing
End-to-End QC & Forensic Watermarking
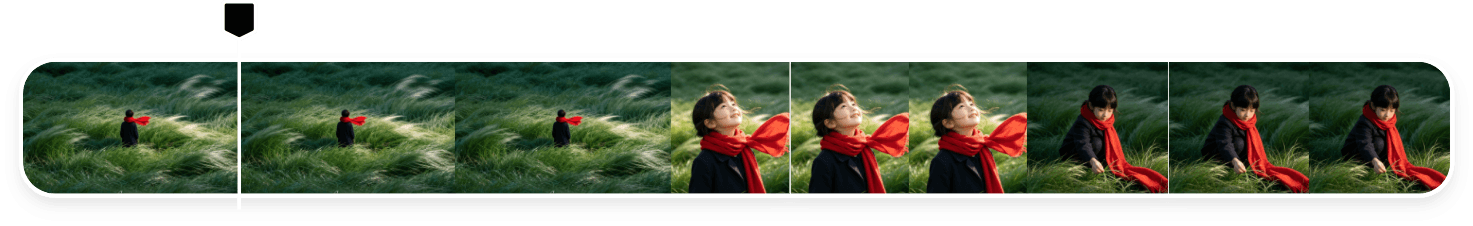
Cut these shots together and add the BGM I provided
Content Understanding
Smart Segmentation
Highlight Reels
Semantic Subtitle Search
AI Dedup & Archiving
Adaptive Reframing
Pre-Moderation
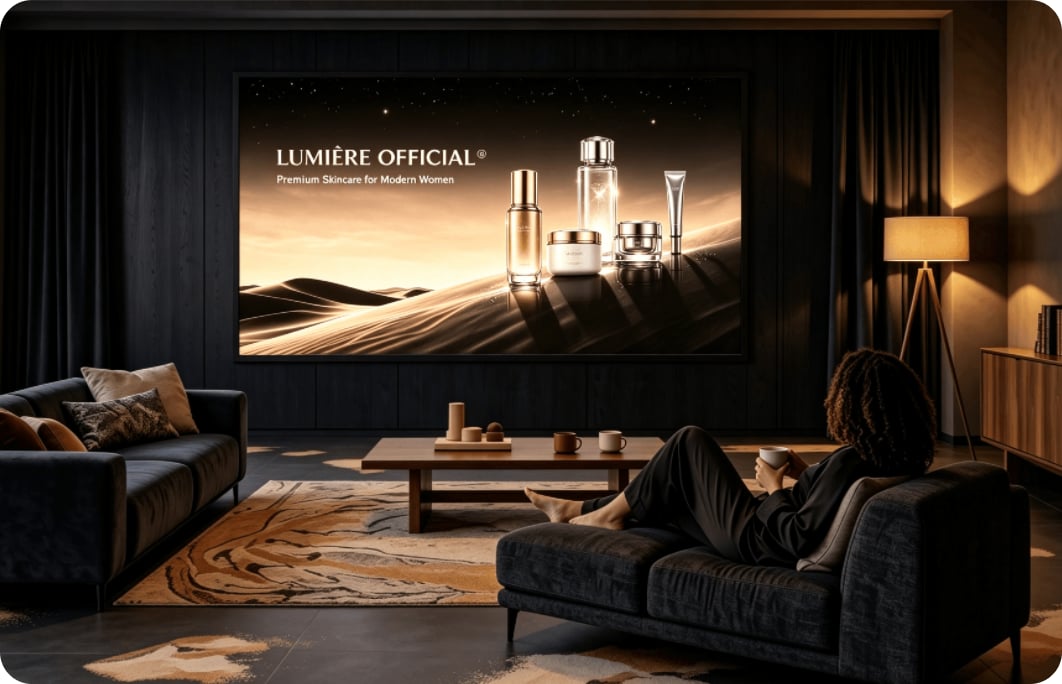
 Ad for single women
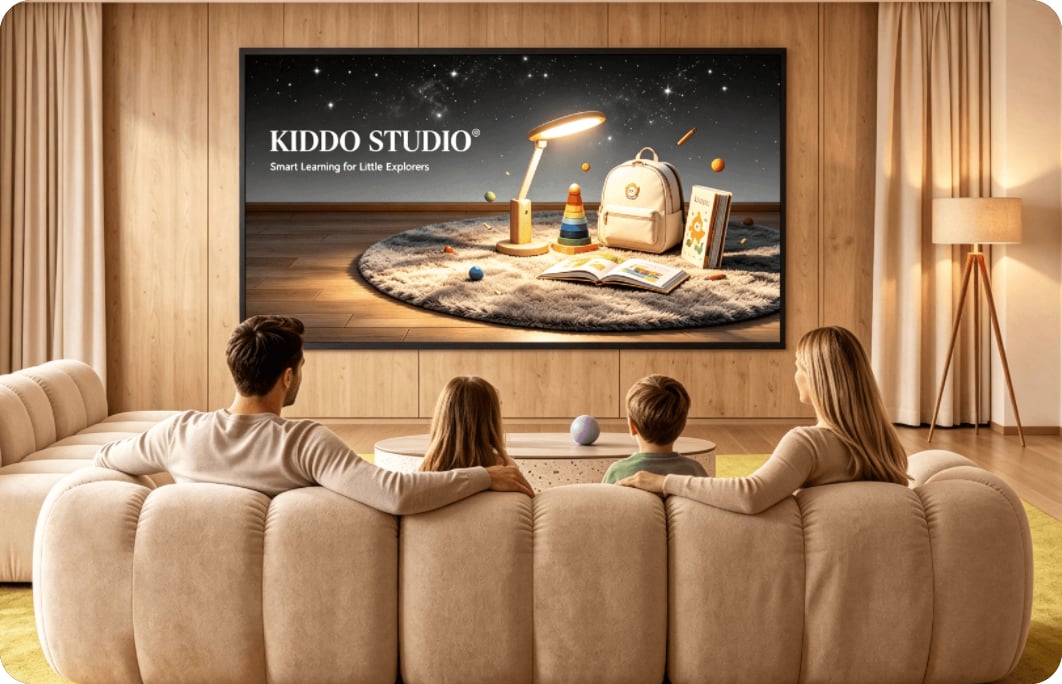 Ad for families with kids
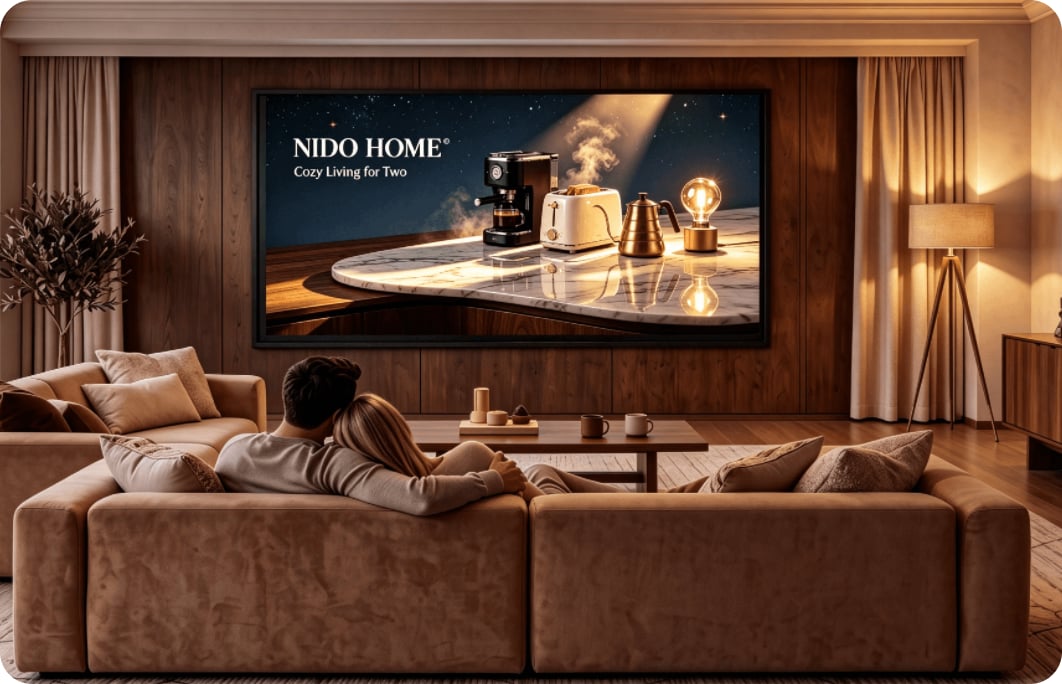 Ad for married couples
Smart Signal Ingest & Protocol Conversion
Smart Routing & Failover
Real-Time Live Stream Understanding
Live 4K Super-Resolution
Server-Side Ad Insertion (SSAI)
Watermark & Trace
E-commerce Creative Agent
Backed by world-class scale, effortless to use
800M+Minutes processed daily
90%+Powering leading video platforms
20+yrsTechnology and data expertise
No.1Market share in IDC reports for consecutive years
Use in an Agent
No API integration needed — a single prompt lets your Agent install and invoke every WAND capability automatically.
Follow https://skillhub.cn/install/skillhub.md to install @tencent-adm/tencent-mps-intl.
More Integration Options
Install with a single command and integrate quickly into local projects and CI pipelines.
Command-line integration is on the way
Global Compliance Certifications
Deploy your business with confidence
 CREATE A BETTER WORLD
A one-stop media AI platform — from creation to delivery